Central Data Management
Core Project 4 – The so-called Core Projects of the Biodiversity Exploratories (BE) emerged from the on-site project selection and the establishment of the exploratories (2006-2008) and have been providing the infrastructure since 2008.

Each year, the projects within the Biodiversity Exploratories (BE) generate large amounts of research data covering a wide range of scientific questions. Centralized data management is essential to ensure that these data are managed according to the FAIR principles (Findable, Accessible, Interoperable, and Reusable), facilitating data sharing and reuse among researchers.
Equally important is the long-term preservation of these data, making them available to future generations of researchers both within and beyond the BE. Long-term datasets and time series are particularly valuable for addressing many questions in biodiversity research.
To support these goals, the Central Data Management project has been an integral part of the BE since its establishment. As one of the central infrastructure projects, it is based at Friedrich Schiller University Jena, Germany, and serves as the main point of contact for all aspects of research data management for BE participants, external researchers, and the interested public.

We achieve the main goals described above regarding the storage and exchange of the research data with a web application called BExIS. Below you will find sections with additional information on this.
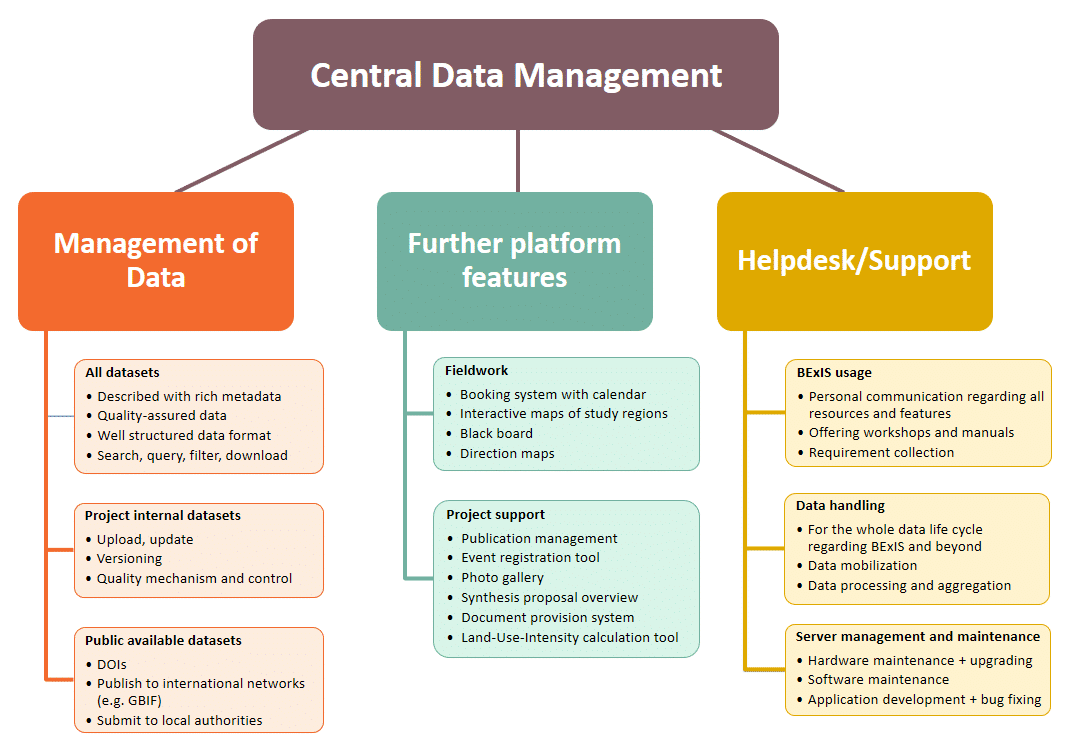
We support researchers in using BExIS and in all data management issues. We offer help in uploading data into BExIS and ensure high data quality (data curation). Last but not least, we advise and support researchers in publishing their data.
In addition to the research data support, we promote the exchange of important documents and publications in the overall project and offer software tools for querying basic data, such as climate data. Furthermore, we support the researchers by providing important information and tools for planning and conducting fieldwork in BExIS. These aspects are shown in the following figure and explained in more detail in the ‘Functionalities of BExIS section’.

BExIS is the abbreviation of our information system name ‘Biodiversity Exploratories Information System’. Initially, the software was developed and continuously extended in the BE project since 2007 (BExIS, 1st generation). Other research projects also showed interest in such an application. But it was not easy to set up BExIS for other projects, as it was developed for the demands of the BE. Hence, a DFG project was initiated in 2012 with the participation of our team. The goal was to develop a modular data management system for ecological data that can be easily adapted to the needs of different projects.
The new software was named BEXIS2 and is a freely available, server-based research data management application. It is designed to support the entire data life cycle and is highly configurable. Among other things, it supports the use of different metadata schemas, access to different versions of the data, predefinition of variables, rights assignment with an integrated release request and release management for datasets, search configuration, and DOI assignment.
In February 2021, the BE project started to use the BEXIS2 software. However, the name ‘BExIS’ continues to stand for the BE’s information system. Since the BExIS2 software is modular, we extended it with our BE-specific functionalities (see section ‘Functionalities of BExIS’) and made them available to other projects using BEXIS2.
If you are interested in the development of the platform, you can get an overview on the GitHub pages:

In the current phase (2026-2029), we continue to focus on providing a reliable and sustainable infrastructure for managing BE research data. This includes the operation and further development of BEXIS2, user support, and active data curation to ensure the long-term preservation and quality of research data.
An important focus is on improving the accessibility, discoverability, and reusability of BE data, both within the BE and beyond. We aim to further enhance data search and discovery, improve data and metadata quality, and support data publication and interoperability with external research data infrastructures. The integration and use of persistent identifiers (PIDs) will also be further developed to improve the identification and linking of research resources.
In addition, we will continue to develop tools to support collaboration, research, and resource sharing within the BE. We also plan to explore the potential of artificial intelligence (AI) to support data curation, particularly by assisting in assessing and improving metadata quality.
Throughout these activities, we aim to further promote the FAIR principles and Open Science, making BE data increasingly findable, accessible, interoperable, and reusable for the wider research community.

BEXIS2 mainly provides functions for handling data and managing registered persons. An overview of the core functions can be found on the BEXIS2 feature page.
In addition, we develop special functions tailored to the needs of the BE (see goals). Since we also follow the modular approach during programming, these modules are usable by other projects. An overview of existing BEXIS2 modules is provided on the BEXIS2 module page. Below you find a brief overview of our developed components.

Public Datasets

Non-public datasets

Central data management
Central Data Management BExIS
Friedrich-Schiller-University of Jena
Dept of Mathematics and Computer Science
Inselplatz 5
07743 Jena
Contact:
bexis@listserv.uni-jena.de